Hypercare and Stabilization: Surviving the First 90 Days on S/4HANA
As more organizations race to be live well before the ECC mainstream maintenance deadline, hypercare, the critical stabilization window right after go-live, is the phase most project plans still leave understaffed, with AI-assisted monitoring only helping teams catch problems a little faster.
Hypercare and Stabilization: Surviving
the First 90 Days on S/4HANA
the First 90 Days on S/4HANA
As more organizations race to be live well before the ECC mainstream maintenance
deadline, hypercare, the critical stabilization window right after go-live, is the phase
most project plans still leave understaffed, with AI-assisted monitoring only helping
teams catch problems a little faster.
7 min read | Orpington Technologies Insights
deadline, hypercare, the critical stabilization window right after go-live, is the phase
most project plans still leave understaffed, with AI-assisted monitoring only helping
teams catch problems a little faster.
SAP has set December 31, 2027 as the end of mainstream maintenance for ECC, and the network of
consultants, implementation partners, and third-party tools built up around that platform is already
thinning as the installed base shifts toward S/4HANA. Specialists who know ECC-era configuration
inside and out are retraining or moving on to other work, and the support options available to a company
still running ECC in 2028 will look considerably thinner than what's available today. That timeline is why
so many organizations are compressing their migration schedules, which puts pressure on every phase
of the project, including the one that gets the least attention up front: hypercare.
consultants, implementation partners, and third-party tools built up around that platform is already
thinning as the installed base shifts toward S/4HANA. Specialists who know ECC-era configuration
inside and out are retraining or moving on to other work, and the support options available to a company
still running ECC in 2028 will look considerably thinner than what's available today. That timeline is why
so many organizations are compressing their migration schedules, which puts pressure on every phase
of the project, including the one that gets the least attention up front: hypercare.
Hypercare is the stabilization period right after go-live, when a system finally carries full production
volume for the first time. No test script perfectly replicates the mess of live business activity, so issues
testing never caught start surfacing within the first few days, and the team has to catch and resolve
them before they compound into something that undermines confidence in the new platform. Staffing
that window well is genuinely hard: ticket volume is unpredictable, the mix of real defects and training
gaps is difficult to sort quickly, and most project budgets treat hypercare as a short tail rather than a
distinct phase with its own resourcing needs. How an organization handles those first weeks tends to set
the tone for the platform's next several years, and AI-assisted monitoring tools are starting to help some
teams catch developing problems sooner, though they don't change who has to staff the response.
Page 1 of 4
volume for the first time. No test script perfectly replicates the mess of live business activity, so issues
testing never caught start surfacing within the first few days, and the team has to catch and resolve
them before they compound into something that undermines confidence in the new platform. Staffing
that window well is genuinely hard: ticket volume is unpredictable, the mix of real defects and training
gaps is difficult to sort quickly, and most project budgets treat hypercare as a short tail rather than a
distinct phase with its own resourcing needs. How an organization handles those first weeks tends to set
the tone for the platform's next several years, and AI-assisted monitoring tools are starting to help some
teams catch developing problems sooner, though they don't change who has to staff the response.
 Orpington Technologies | SAP S/4HANA Migration Insights
© Orpington Technologies Inc. www.orpingtontech.com
What Hypercare Is Actually For, and Why It's Hard to Staff
Hypercare exists because a migration team knows, going in, that some issues will only show up under
real production conditions: an integration touchpoint that behaves differently at peak volume, a custom
report that times out against the full data set instead of a test sample, an edge case in a business
process nobody thought to test because it only happens at month-end. The team staffs up specifically to
catch and resolve these fast, before they compound.
real production conditions: an integration touchpoint that behaves differently at peak volume, a custom
report that times out against the full data set instead of a test sample, an edge case in a business
process nobody thought to test because it only happens at month-end. The team staffs up specifically to
catch and resolve these fast, before they compound.
The staffing challenge is that ticket volume in the first days after go-live is both high and unpredictable in
its makeup: a mix of genuine defects, training gaps showing up as "the system is broken" tickets, and
configuration questions that have nothing to do with a defect at all. Route everything through the same
triage queue, which is what most traditional hypercare models do, and genuine defects end up sitting
behind a backlog of questions a well-designed self-service tool could have resolved on its own.
Where the Support Model Has to Change
its makeup: a mix of genuine defects, training gaps showing up as "the system is broken" tickets, and
configuration questions that have nothing to do with a defect at all. Route everything through the same
triage queue, which is what most traditional hypercare models do, and genuine defects end up sitting
behind a backlog of questions a well-designed self-service tool could have resolved on its own.
The traditional hypercare model puts one tier of support in front of every incoming ticket, whether it's a
genuine defect, a training gap, or a question the documentation already answers. That works fine at low
volume. It breaks down in the first two weeks after go-live, when ticket counts spike and the team
doesn't yet have enough history with the live system to sort quickly between something that's actually
broken and someone who needs a five-minute walkthrough. Splitting the queue earlier by ticket type,
rather than by whoever picks it up next, is one of the more reliable fixes, and it usually means adding a
dedicated triage step most projects don't budget for.
genuine defect, a training gap, or a question the documentation already answers. That works fine at low
volume. It breaks down in the first two weeks after go-live, when ticket counts spike and the team
doesn't yet have enough history with the live system to sort quickly between something that's actually
broken and someone who needs a five-minute walkthrough. Splitting the queue earlier by ticket type,
rather than by whoever picks it up next, is one of the more reliable fixes, and it usually means adding a
dedicated triage step most projects don't budget for.
The other thing that breaks under real production load is visibility. Batch jobs, interfaces, and custom
reports often behave differently at full volume than they ever did in testing, and a team relying only on
inbound tickets to learn about problems finds out about them later than it should. Some hypercare teams
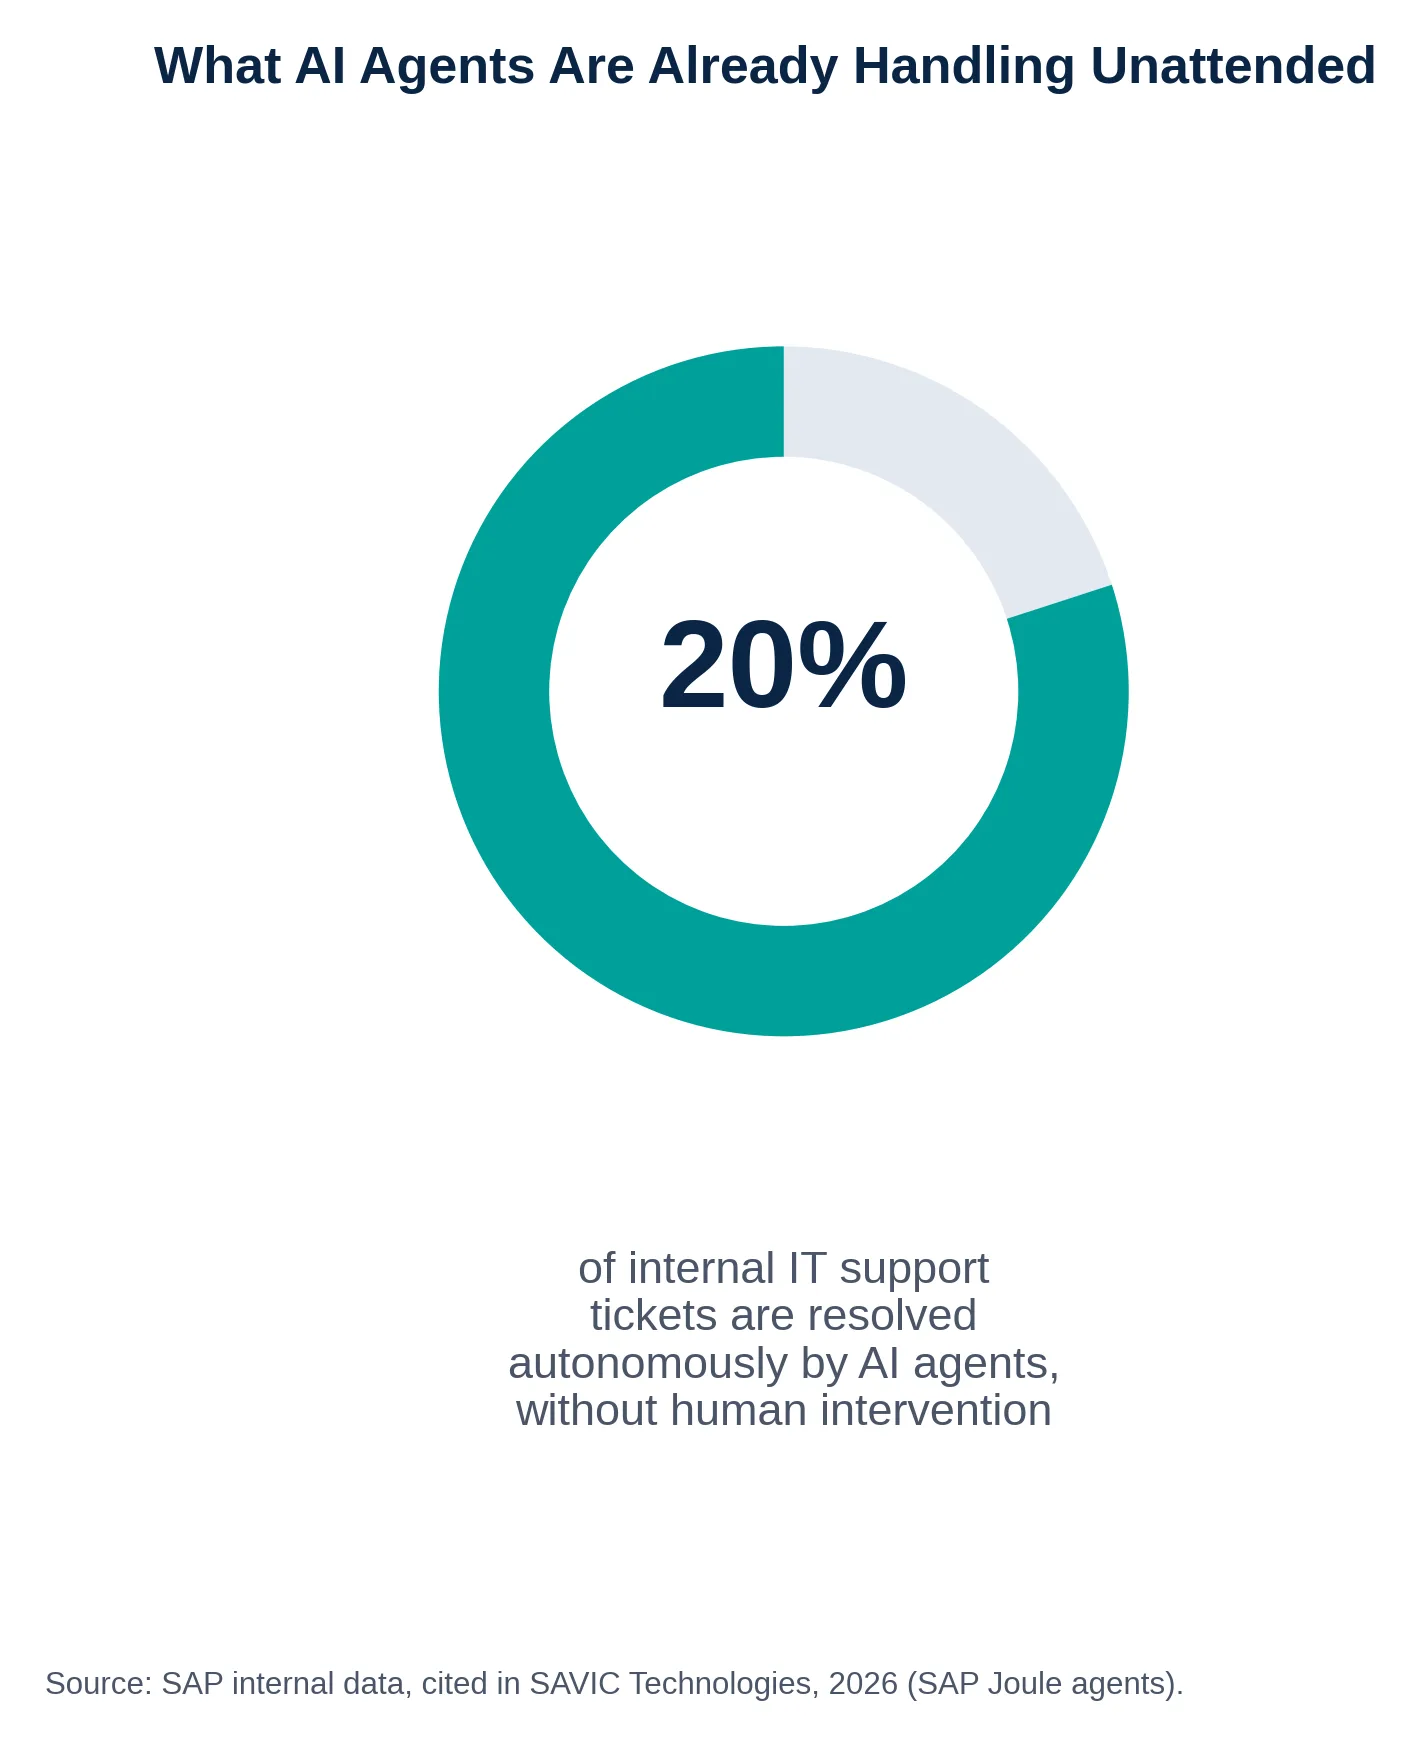
now layer in AI-assisted monitoring, tools trained on expected system patterns like job completion times
and error rates, to flag anomalies before enough users notice to file a ticket, and a smaller number use
AI to deflect the simplest, most repetitive questions before they reach a person. Both are useful
additions. Neither replaces the underlying staffing and triage model; they just take some pressure off it.
Page 2 of 4
reports often behave differently at full volume than they ever did in testing, and a team relying only on
inbound tickets to learn about problems finds out about them later than it should. Some hypercare teams
now layer in AI-assisted monitoring, tools trained on expected system patterns like job completion times
and error rates, to flag anomalies before enough users notice to file a ticket, and a smaller number use
AI to deflect the simplest, most repetitive questions before they reach a person. Both are useful
additions. Neither replaces the underlying staffing and triage model; they just take some pressure off it.
 Orpington Technologies | SAP S/4HANA Migration Insights
© Orpington Technologies Inc. www.orpingtontech.com
Where the Value Shows Up Fastest
The functions that stabilize fastest tend to be the ones with high-volume, rule-governed transaction
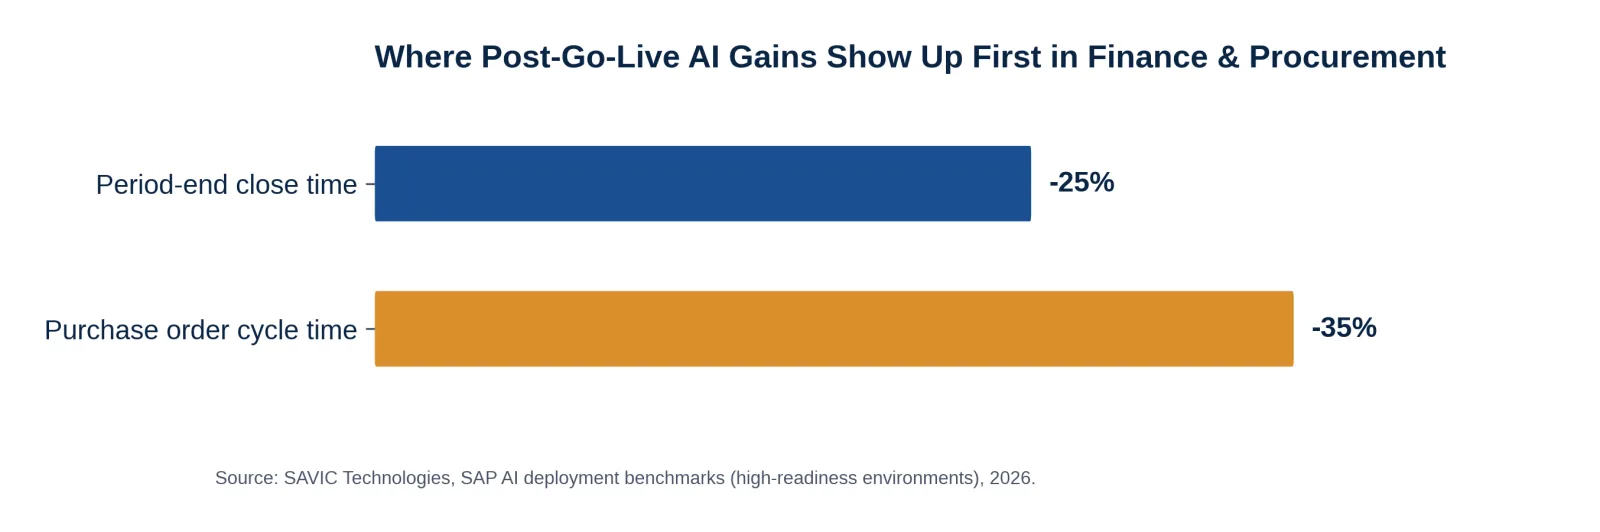
flows, and finance and procurement are the clearest examples. Benchmarking of high-readiness
post-go-live environments, cited by SAVIC Technologies, found a 20–30% reduction in period-end
closing time and a 30–40% reduction in routine purchase order cycle time once tighter monitoring and
exception handling were embedded into those processes. Those gains compound month over month
once stabilization is complete, well past the hypercare window itself.
flows, and finance and procurement are the clearest examples. Benchmarking of high-readiness
post-go-live environments, cited by SAVIC Technologies, found a 20–30% reduction in period-end
closing time and a 30–40% reduction in routine purchase order cycle time once tighter monitoring and
exception handling were embedded into those processes. Those gains compound month over month
once stabilization is complete, well past the hypercare window itself.
That's a useful signal for where hypercare resources pay off fastest: high-volume, well-defined
transaction flows return value quickly. Low-volume, judgment-heavy processes are still better served by
keeping an experienced person in the loop from day one, whatever tooling sits alongside them.
The Failure Mode to Watch For
transaction flows return value quickly. Low-volume, judgment-heavy processes are still better served by
keeping an experienced person in the loop from day one, whatever tooling sits alongside them.
A support model that closes tickets quickly can still hide a systemic problem, if nobody is watching the
pattern behind the individual resolutions. Twenty tickets closed as "user error, retrained" might actually
be twenty symptoms of one configuration issue that never gets fixed, because no single ticket looked
significant enough to escalate on its own. That risk gets worse, not better, when part of the triage
volume is handled by an AI agent instead of a person, since fast resolutions don't automatically surface
a pattern across them. The hypercare teams that avoid this trap run a human-led root-cause review of
ticket trends every week, no matter how much of the routine volume is automated.
Where This Leaves You
pattern behind the individual resolutions. Twenty tickets closed as "user error, retrained" might actually
be twenty symptoms of one configuration issue that never gets fixed, because no single ticket looked
significant enough to escalate on its own. That risk gets worse, not better, when part of the triage
volume is handled by an AI agent instead of a person, since fast resolutions don't automatically surface
a pattern across them. The hypercare teams that avoid this trap run a human-led root-cause review of
ticket trends every week, no matter how much of the routine volume is automated.
Orpington Technologies works with clients on hypercare staffing models and escalation design as part
of pre-go-live readiness, because the gap between a well-planned stabilization period and a reactive
one shows up fast, and expensively, in the first weeks after cutover. With ECC mainstream maintenance
ending December 31, 2027 and support options for the platform narrowing well before then, that
Page 3 of 4
of pre-go-live readiness, because the gap between a well-planned stabilization period and a reactive
one shows up fast, and expensively, in the first weeks after cutover. With ECC mainstream maintenance
ending December 31, 2027 and support options for the platform narrowing well before then, that
Orpington Technologies | SAP S/4HANA Migration Insights
© Orpington Technologies Inc. www.orpingtontech.com
planning window keeps getting shorter. Orpington brings deep S/4HANA migration and cutover
experience, a tested hypercare methodology, and AI-assisted delivery tools, among other
differentiators, to help clients land safely on the other side. Learn more about Orpington's approach at
orpingtontech.com.
Sources & Further Reading
[1]
SAVIC Technologies — SAP AI ROI: Real Numbers, Enterprise Reality Check, 2026
[2]
PerfecTwin — SAP Hypercare Testing Strategy: How to Cut Your Stabilization Period in Half
Page 4 of 4
experience, a tested hypercare methodology, and AI-assisted delivery tools, among other
differentiators, to help clients land safely on the other side. Learn more about Orpington's approach at
orpingtontech.com.